hummin
A GLM-native terminal coding agent. Local inference is a first-class citizen, not a compatibility mode: colibri, llama.cpp and Ollama on your own hardware, surfaced in one model picker alongside Z.ai's GLM catalog.
See it in action
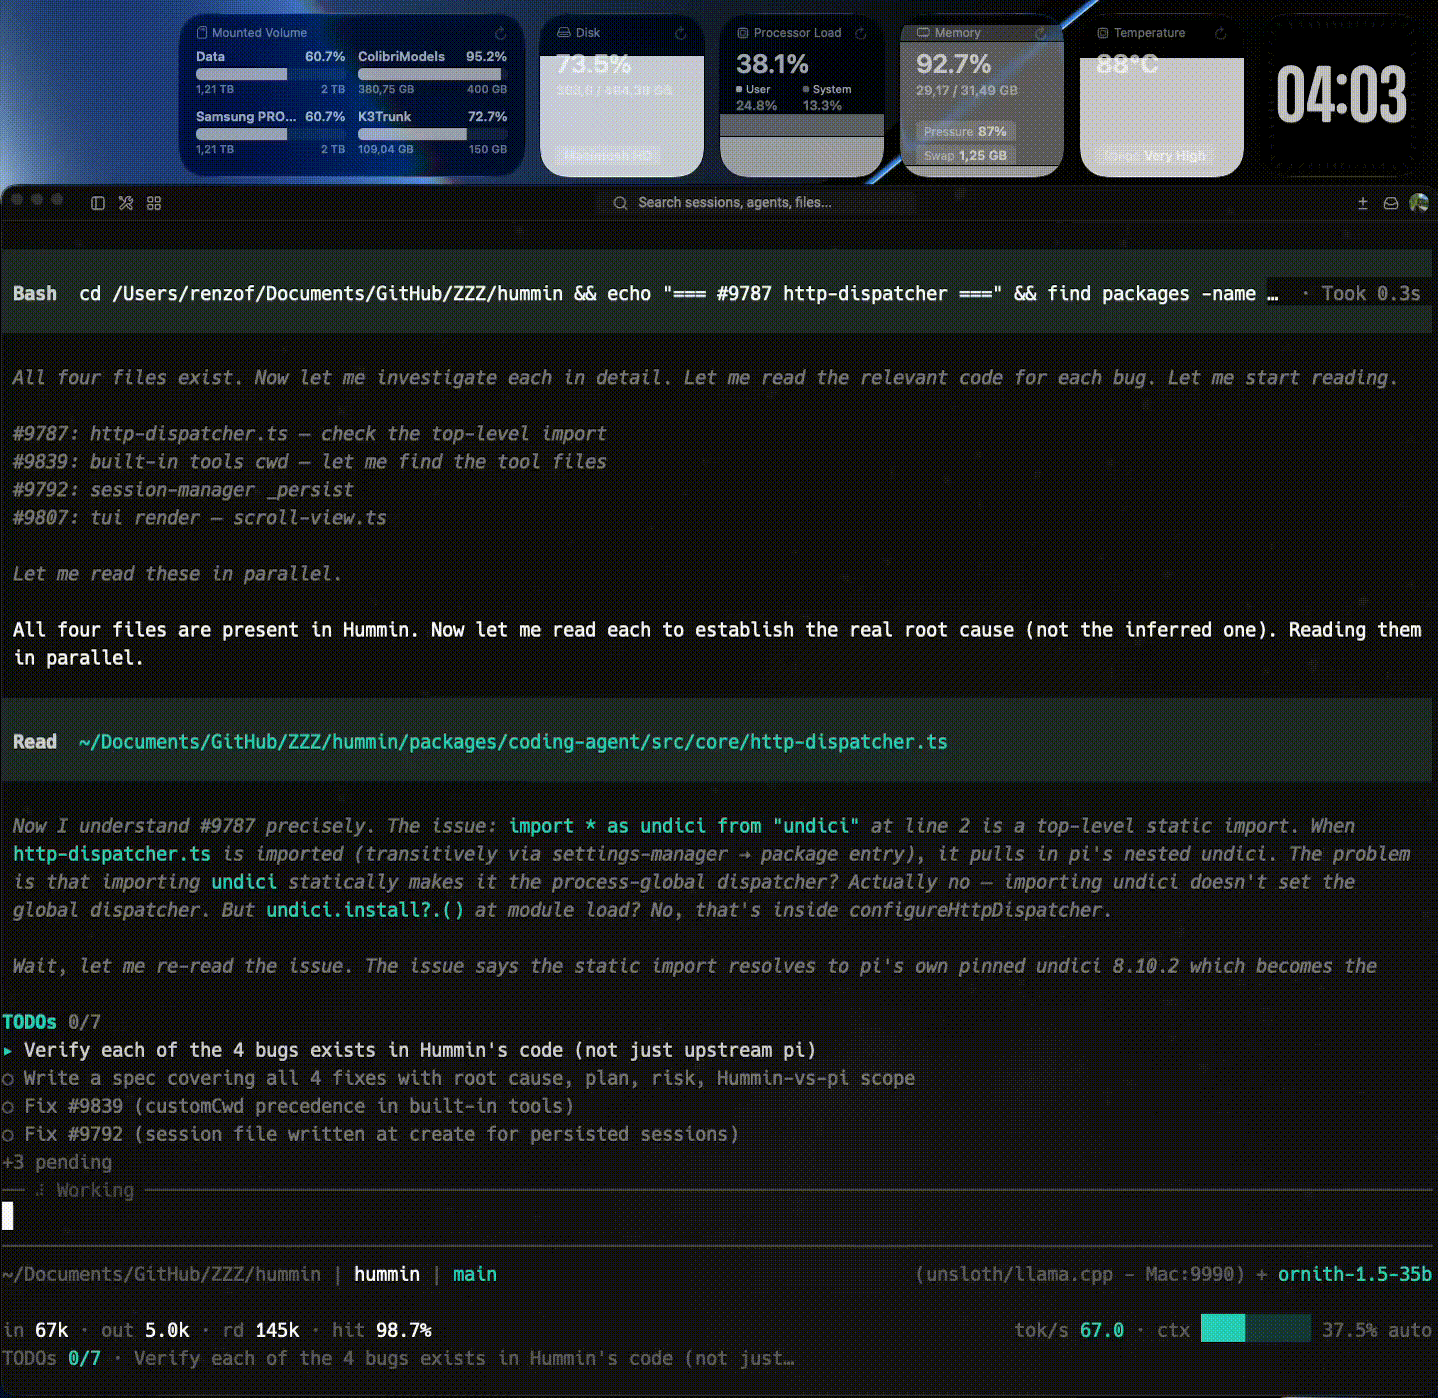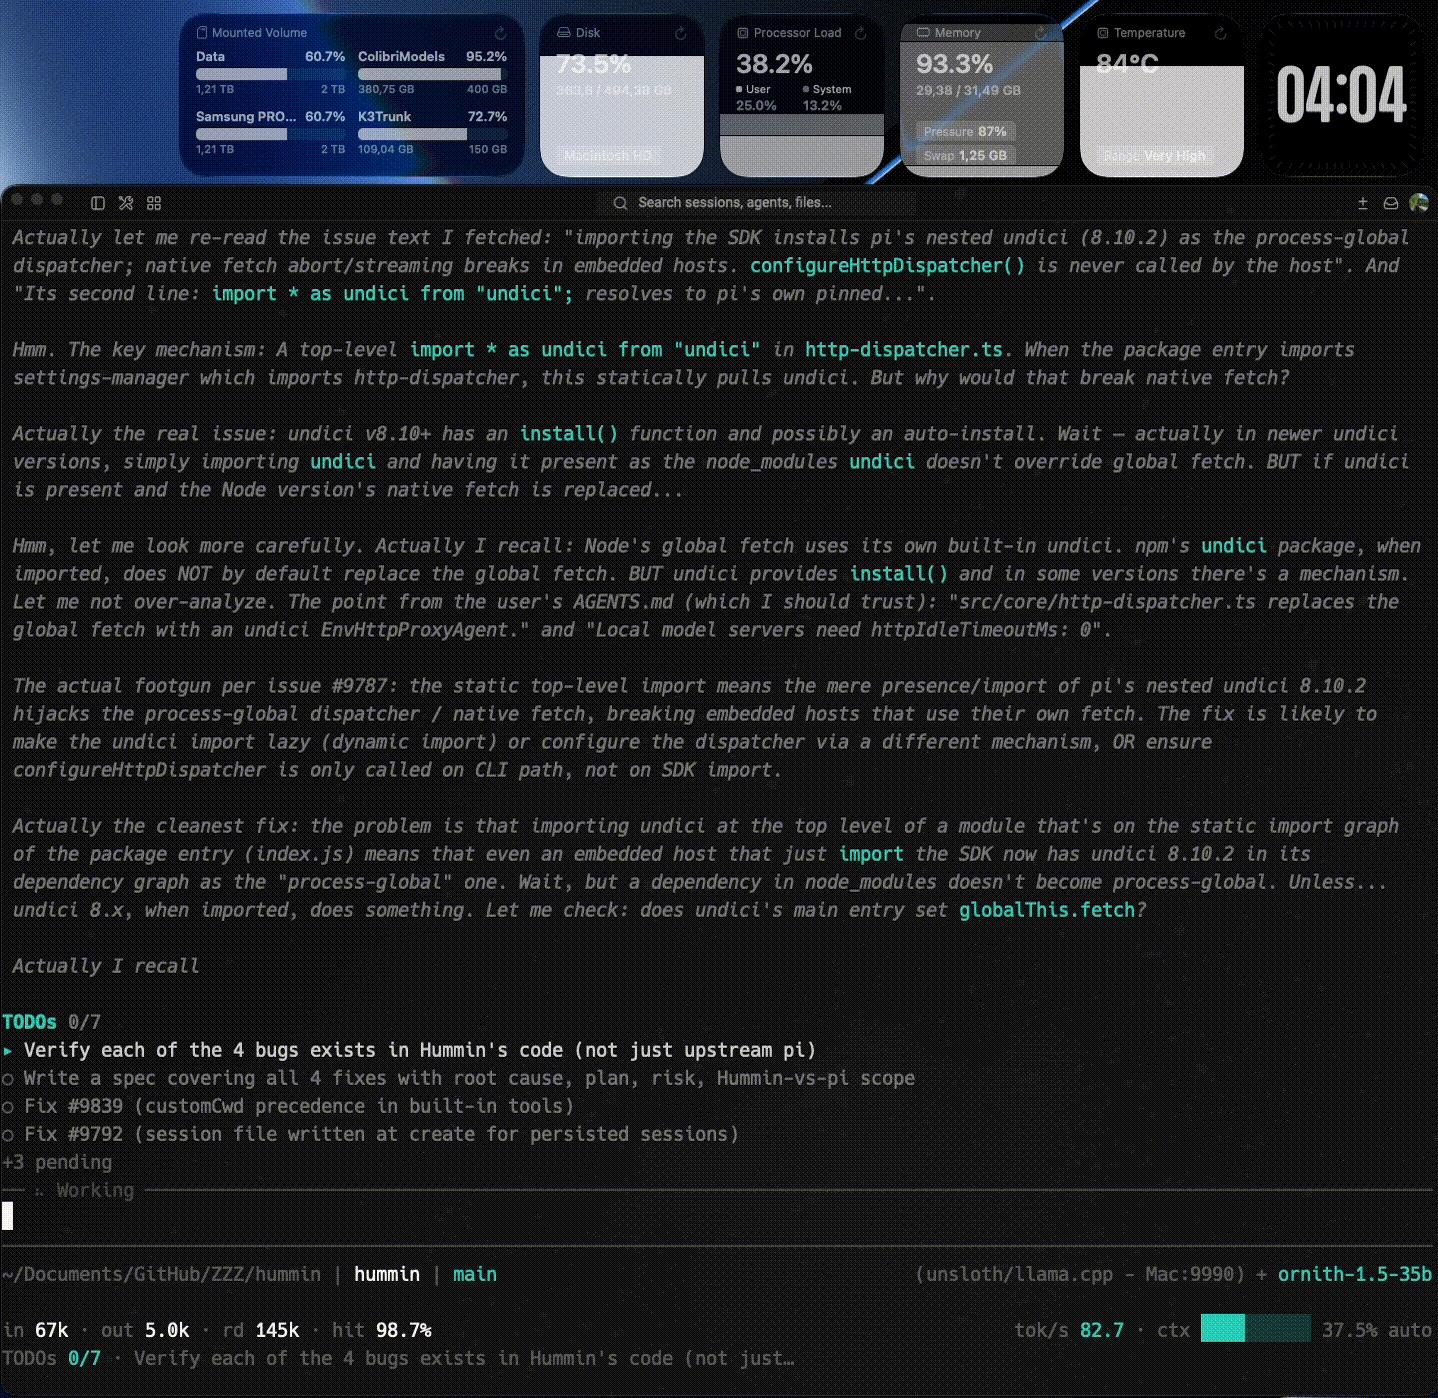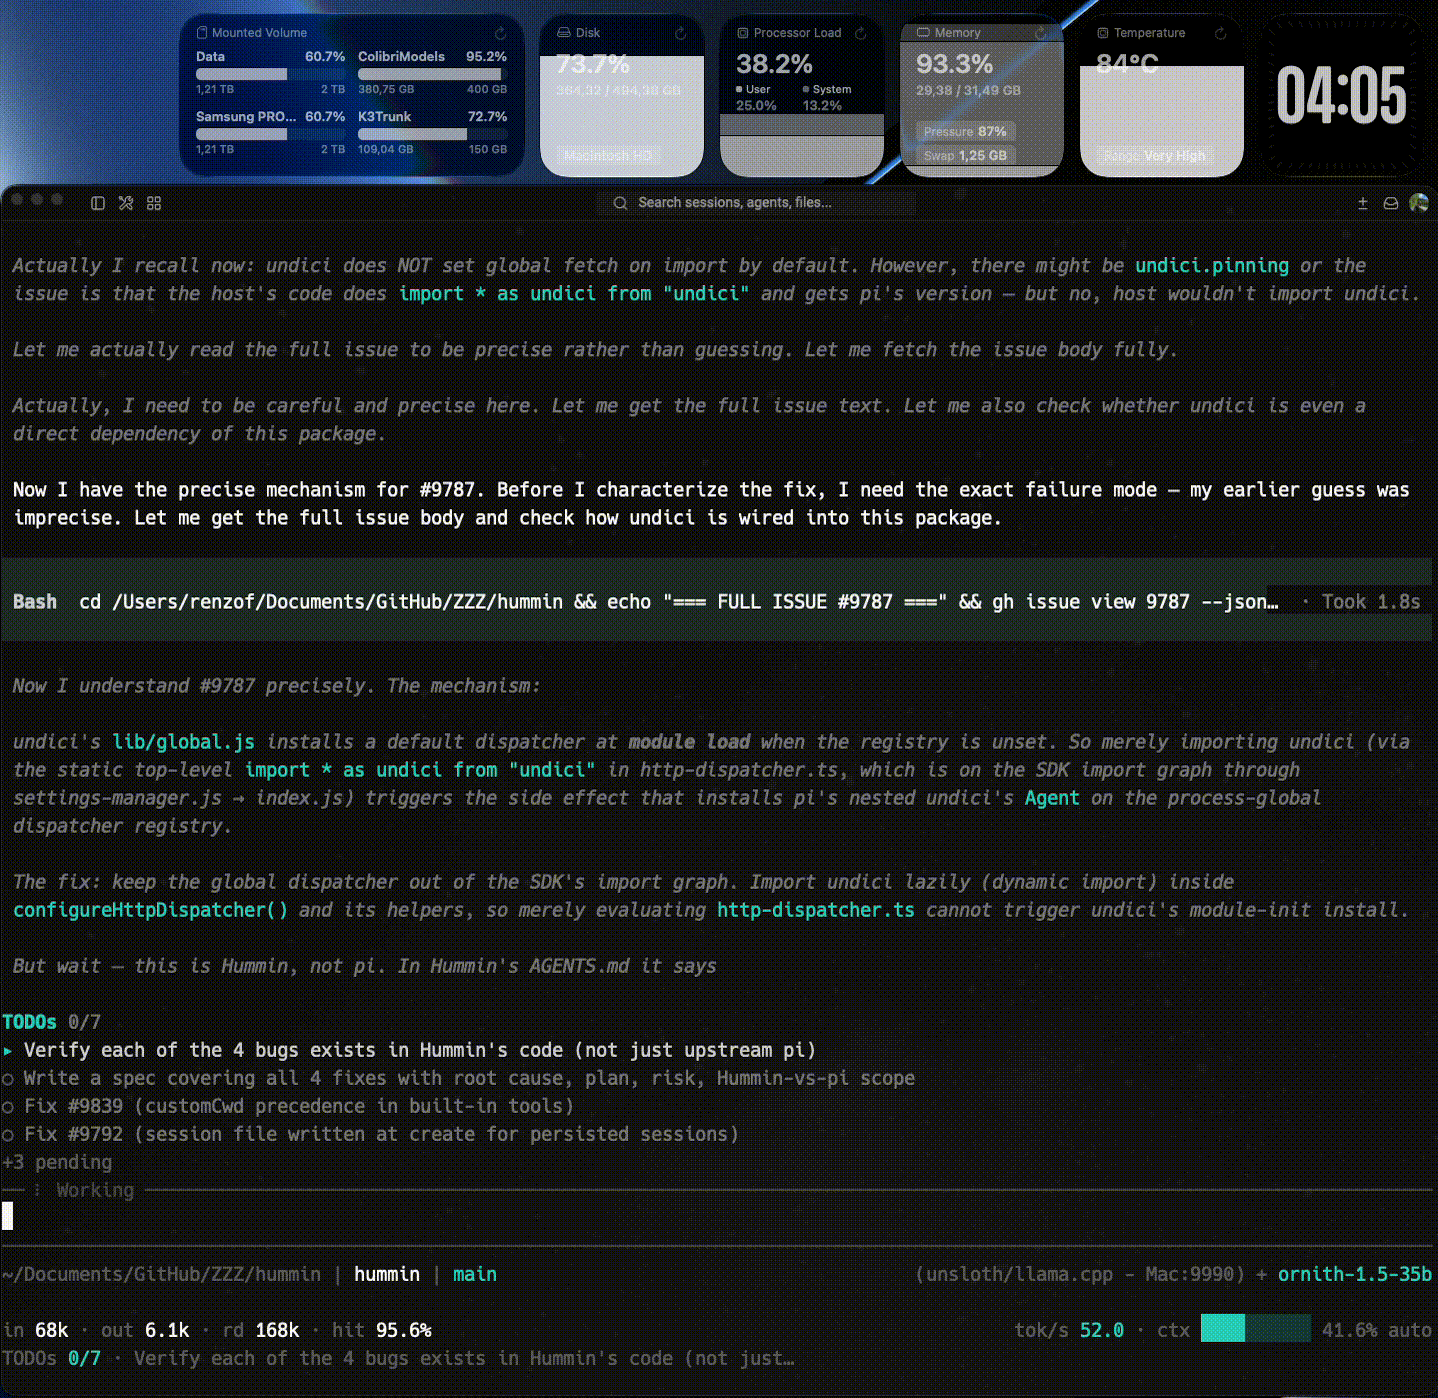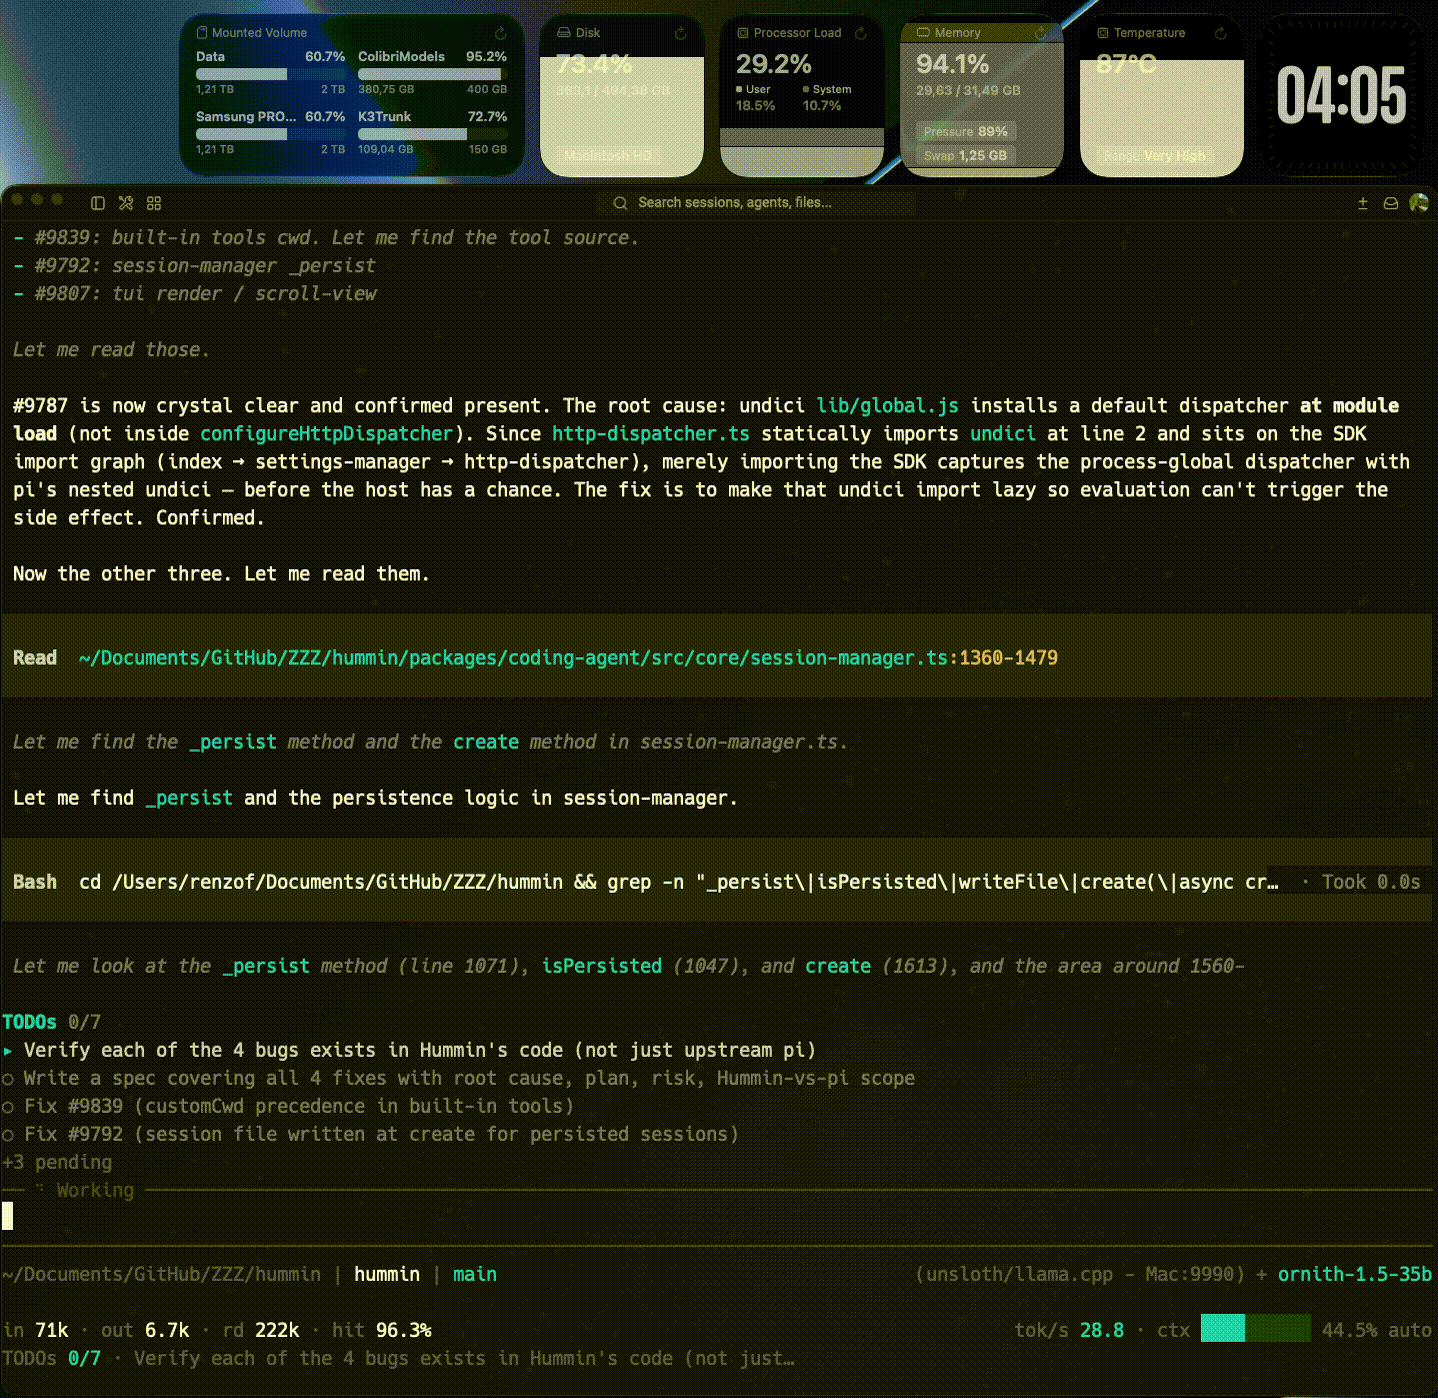
Ornith 1.5 35B (local GGUF via llama.cpp) working through four upstream bugs in hummin's own source. Watch the footer: live tok/s next to the context bar - 31 tok/s from a model running on a Mac Mini. The full path to this setup is in Local Models.
Why hummin
-
GLM first
GLM-5.3, GLM-5.3-Flash and GLM-5.3-highspeed ship in the built-in
zaicatalog with 1M-token context and mapped reasoning variants. The default model is GLM. -
Local fleet
One provider across every OpenAI-compatible server on your LAN: health-probed, serialized per origin, startable straight from the model picker.
-
Agent teamwork
Sessions message each other across terminals and projects, share a task board, spawn bounded subagents, run scheduled wake-ups.
-
Safety that bites
Seatbelt/bubblewrap sandboxing, destructive-command advisories, loop and budget guardrails, checkpoints with
/rewind. -
Memory that persists
Session distillation into lessons plus a self-curating Obsidian-compatible vault with BM25-ranked recall.
-
Built for slow models
Queue-aware UX, real context windows, idle-timeout tuning and a local-vs-cloud cost split - because a 195GB model streams from disk.
From zero to a local model in the terminal
-
Resumable
hf download, stall-proof flags, the right machine for the WAN pipe. -
llama.cpp on Mac (launchd) or Linux (compose); colibri for frontier MoE.
-
One env var,
/model, done. Fleet start/stop from the picker. -
Service templates, co-run rules, warm caches, measured numbers.